Back to home

Current value · September 2026

I turn difficult questions into useful, checkable results.

I curate capabilities by connecting human judgment, AI, formal methods, and custom tools. I choose the question, bring together the right tools, and check what the results support.

Engineer, philosopher, and futurist. My work connects research, systems design, and intelligence augmentation: expanding what I can understand, build, and verify.

The value in the combination

I can do more with the right tools.

I bring together the models, tools, and checks a problem needs. My projects show some of these combinations in use. The same capabilities can help me explore new questions, learn, create, and make better decisions.

I decide which question is worth asking, how to represent the problem, which tool can check the claim, and when there is enough evidence to proceed.

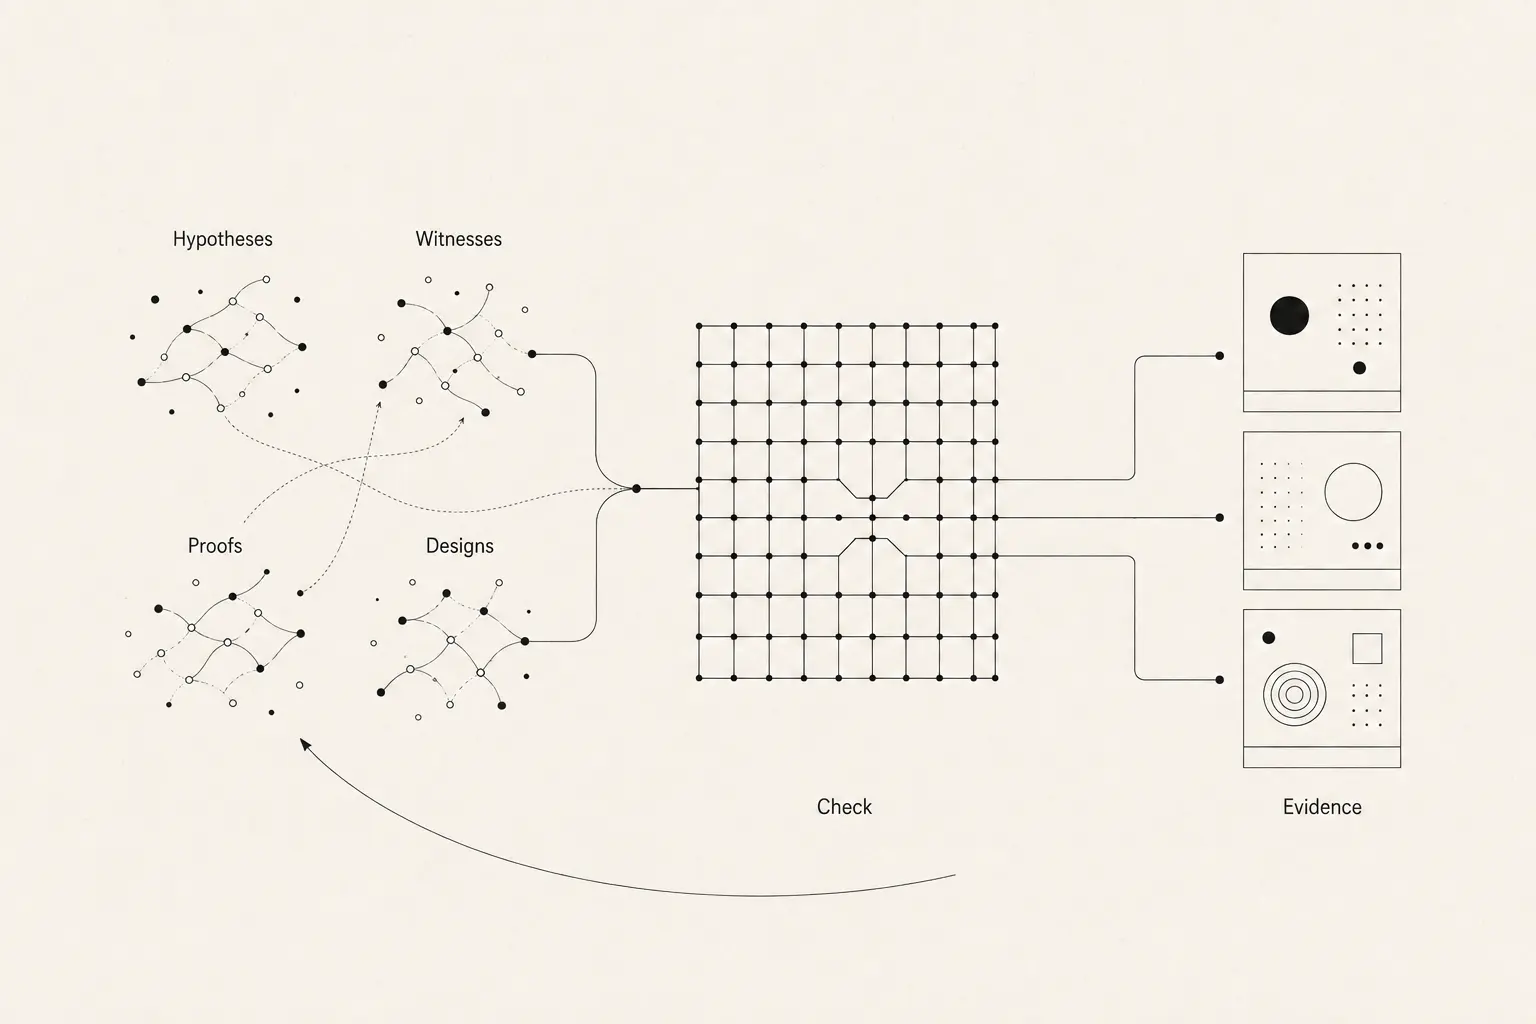
Candidate hypotheses, witnesses, proofs, and designs connect to a checker and evidence artifacts.
LLMs explore and recombine candidates. Formal tools check specified claims. I choose the question, the representation, and the evidence standard. View larger.

Where I can contribute

What I can help you do.

Here are some ways I put these capabilities to use, with examples you can inspect.

Research & discovery

Make a difficult question testable.

Develop competing hypotheses, useful abstractions, predictions, and counterexamples with LLM assistance. Distinguish a checked mathematical result from provisional support for a scientific model.

Useful output: a precise research question, a bounded experiment or formal model, and a record of what survived testing.

Systems & verification

Make generated work easier to trust and review.

Design explicit state transitions, policy boundaries, and independent checks. Use Lean, Z3, Tau, tests, and replay according to what the particular claim requires.

Useful output: a scoped implementation or review with reproducible checks, failure cases, assumptions, and remaining obligations.

Research infrastructure

Build on what I learn.

Connect models and symbolic tools to durable research memory. My custom Research Kernel Protocol MCP preserves questions, evidence, dependencies, and refutation attempts so later work can build on the record.

Useful output: a workflow and research record that can be inspected, continued, and adapted to another problem.

Communication & decision support

Make difficult ideas clear.

Translate difficult concepts into explanations, diagrams, interactive examples, and maps connecting claims to evidence. Help a reader understand the result, question its assumptions, and decide what to do next.

Useful output: a technical explanation or decision brief with an understandable model and evidence you can inspect.

My contribution

Where I come in.

I guide the workflow today: choose the problem, connect ideas across domains, decide which capabilities to assemble, and review the implications of the result. LLMs help propose, predict, analyze, recombine, and implement.

Deterministic tools establish specified formal properties. Empirical observations and demanding tests provide evidence about scientific models. I keep those forms of evidence distinct when deciding what can be claimed.

The practical value is a clearer decision, an artifact that can be checked, and a capability that can be used again.

Problem selection

Connect a worthwhile objective to a question that can be investigated.

Capability curation

Select and integrate the expertise, models, tools, and representations that fit.

Evidence judgment

Assess what a proof, test, prediction, or counterexample actually establishes.

Continuity

Preserve useful results and failed approaches so the next investigation starts with more knowledge.

How the value can grow

Do more, and keep the quality.

A useful model, checker, or research tool can help with many future questions. Each improvement gives me something to build on next time.

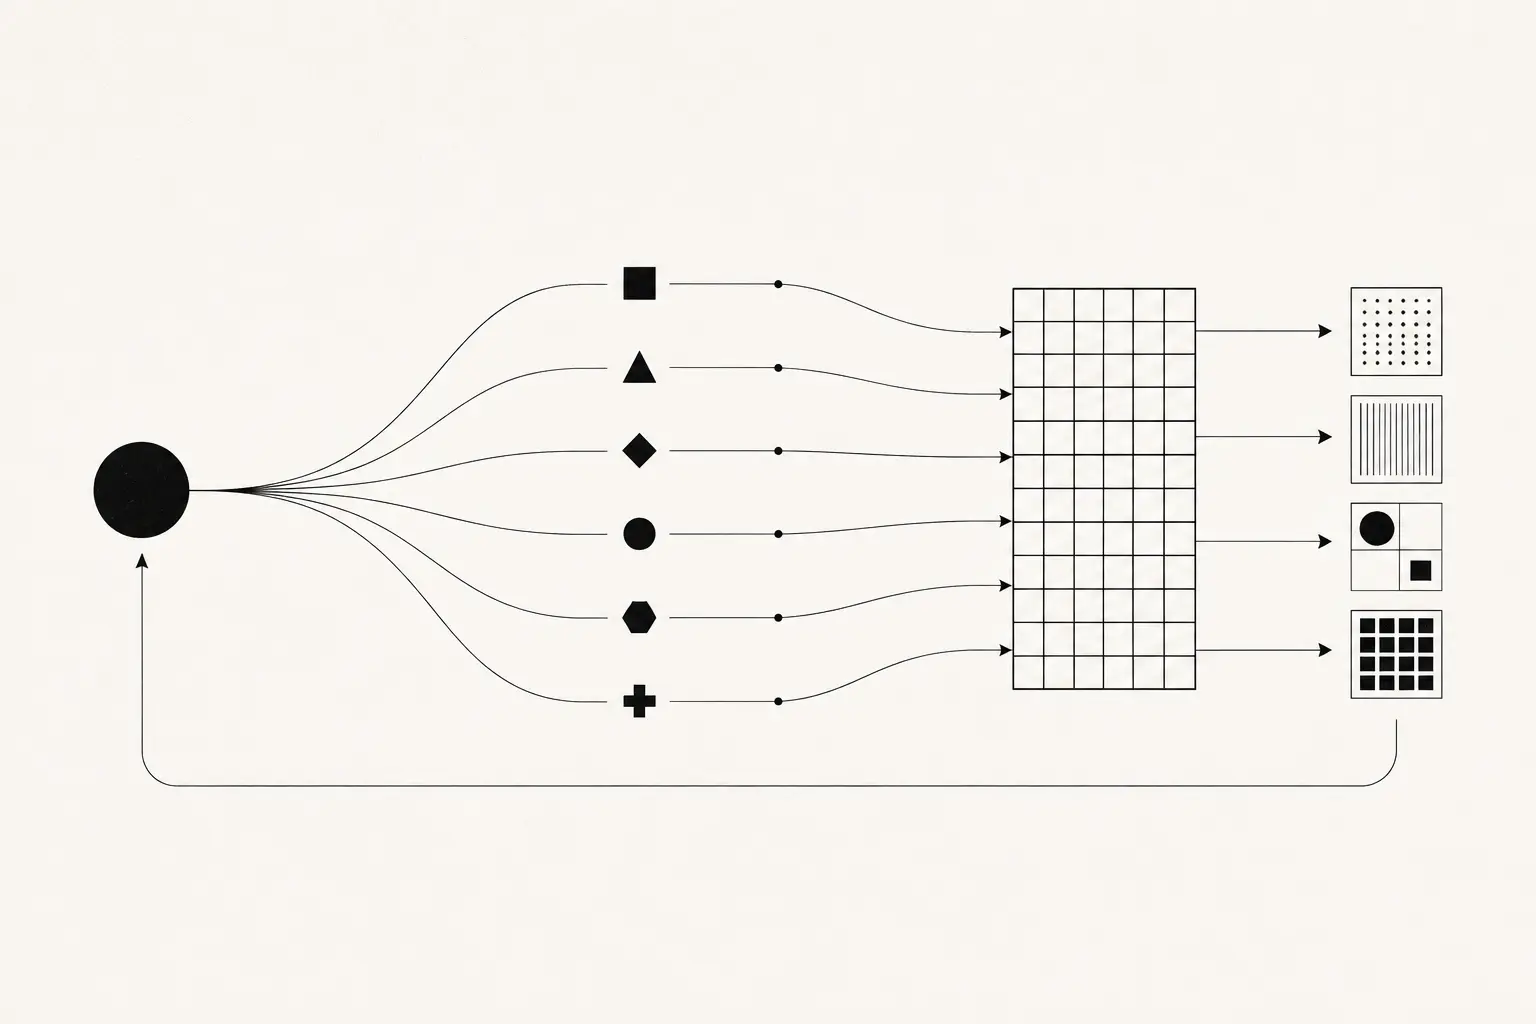
Human direction branches into coordinated agents whose proposals meet shared checks before producing artifacts.
Human direction → coordinated work → shared evidence standards → checked outputs. A conceptual scaling direction. View larger.

Current capability

I guide research using LLMs and symbolic tools. My public repositories, proofs, software, tutorials, and diagrams show that process in use.

Development direction

Transfer more of my workflow to coordinated agents through prompting, tools, and training. The constitutional-training study and full swarm transfer remain research goals. Their gains need to be demonstrated.

I would measure successful scaling by independently accepted outputs, useful task completion, defect rates, review effort, and compute cost. I judge progress by the usefulness and reliability of the results.

Cost model · Updated September 6, 2026

What would conventional development cost?

A refreshed version of the earlier code-volume model, covering MPRD, ZenoDEX, and Formal Methods Philosophy. Other portfolio projects and unpublished work are outside this estimate.

Legacy pooled model · USD

$52.1M–$152.5M

Illustrative conventional rebuild-cost scenarios. These are model outputs, not a quote, measured savings, or my market value. The range is not a confidence interval.

The latest public commits contain 909,096 selected nonblank lines across 4,175 files, up 14.0% from 797,416 in June. The count includes comments, tests, proofs, and examples within selected source files; it is a size proxy rather than physical source lines of code or verified authorship.

Scroll the table horizontally to see each estimate.

Per-repository cost scenarios
Repository / pinned commitNonblank linesCost scenarios
MPRDf1a7e9d02e36149,110$7.8M–$20.1M
ZenoDEXee9f81a3164b702,843$39.8M–$114.3M
Formal Methods Philosophyebe66495c74657,143$2.9M–$6.9M
Sum of separate estimates909,096$50.5M–$141.3M

The headline retains the earlier method of pooling all three repositories before applying the formula. That produces a larger number than adding three separate estimates because effort scales nonlinearly. The original June pooled result was $44.5M–$129.7M under the older wage inputs.

Assumptions, sensitivity, and what the estimate can establish

Inputs and calculation

Let K be selected nonblank lines divided by 1,000. The retained Basic COCOMO equations produce person-months: 2.4 × K1.05 for the lower scenario and 3.0 × K1.12 for the higher scenario. Cost equals person-months ÷ 12 × annual wage × labor multiplier. Formula reference.

The BLS May 2025 wage data, checked September 6, 2026, supplies $135,980 at the median and $214,670 at the 90th-percentile threshold. The respective labor multipliers remain 1.50 and 1.38, giving assumed annual labor costs of $203,970 and $296,245. These multipliers are assumptions, not measured employer costs. No inflation forecast is added.

How much the size assumption matters

  • 25% of the counted size: $12.2M–$32.3M
  • 50% of the counted size: $25.2M–$70.2M
  • 100% of the counted size: $52.1M–$152.5M

The smaller-size cases are arbitrary sensitivity checks. They are not measured AI productivity discounts or estimates of how much work a rebuild would actually require.

Limits of this model

These older equations are extrapolated from a nonblank-line proxy and have not been calibrated for my repositories, AI-assisted development, formal proofs, or research artifacts. They do not establish equivalent human engineering years, production readiness, or the cost of reproducing the same functionality with a different design.

The collector retains the June source extensions and path exclusions for comparability. Known vendor, generated, data, internal, and specified derived-runtime paths are excluded; path filters cannot establish that every third-party or generated file is absent. Exact duplicate files remain in this comparison and are reported in the data. There is no semantic deduplication or authorship audit. Tests and proofs are counted within the footprint, without adding a second labor charge.

External audits, legal fees, deployment, and ongoing operations are not separately priced. A useful project quote would require a defined scope, acceptance criteria, a reuse plan, and measured delivery rates.

Evaluation

Put it to the test.

Start with the problem you need solved. Inspect a related artifact, identify my role and the tools involved, then agree on a small project and decide how to assess its results.

Published work provides evidence of particular capabilities. A proof has stated assumptions; a benchmark has a defined scope; a prototype needs further work before deployment. I make those boundaries part of the assessment.

Useful result

Does the output answer the question or enable the intended task?

Checkable support

Can the relevant evidence be inspected or replayed, with its assumptions visible?

Practical cost

How much time, compute, integration work, and review did the outcome require?

Future use

Does the work leave behind knowledge, tooling, or a method that makes subsequent work easier?

  1. 1. Prove

    Build the Lean projects and run TLC on the TLA+ specs. If a proof fails to check, record the failure and investigate before relying on it.

  2. 2. Run

    Execute each repo's test suite, weighting the tamper, replay, and fuzz cases. Regenerate the metrics and diff the JSON.

  3. 3. Break

    Construct an input the gate should reject. Confirm it is rejected. Then read the stated limitations and test whether any are understated.

Repository sources and verification commands

Choose a project relevant to your question. Follow its documented prerequisites and revision-specific instructions, then compare the results with the stated claims.

Sources

RepositoryWhat it is
TheDarkLightX/MPRDAI actions checked against specified rules. Rust core, Lean proofs, and zero-knowledge proofs.
TheDarkLightX/ZenoDEXFormally constrained exchange. Integer-exact settlement, Lean + TLA+, replay certificates.
TheDarkLightX/Research-Kernel-MCPResearch memory for AI assistants. Connected claims and evidence, explicit promotion rules, SQLite persistence, and an append-only event log.
TheDarkLightX/PopperPadScientific memory that records attempts to refute claims. Objects identified by content hashes, a linked event log, and evidence you can replay.
TheDarkLightX/ZenoFCISPublic Rust library for high-assurance functional-core and imperative-shell systems, with canonical boundaries, atomic commit, and replay evidence.
TheDarkLightX/PersonalSiteThis site, plus the cost-model inputs and replay instructions.
Formal Methods Philosophy (blog)Public tutorials and interactive labs on verification, functional architecture, neuro-symbolic AI, and the philosophy of software correctness. Read it online.

Claims and checks

ClaimWhere it livesHow to check it
AI actions reach an executor only through a deterministic verifier. MPRD crates/mprd-core/, proofs/lean/ Read the executor API; confirm it requires a verified receipt as input. Run the crate tests.
Settlement is integer-exact and replayable. ZenoDEX src/, formal/, replay docs Run the public replay; confirm the certificate hash is identical across two clean runs, and changes if you alter an input.
The repositories include machine-checked properties. Lean files in each repo; *.tla specs Build the Lean projects (lake build) and run TLC on the specs. Read the assumptions and the scope of each result.
The value figures are reproducible. PersonalSite cost-model replay instructions Use the pinned repository versions and commands in the instructions, then compare the result with data/cost-estimates.json.
Claim promotion is fail-closed: no SUPPORTED claim without evidence, refutation, and provenance. Research-Kernel-MCP internal/research_kernel_mcp/kernel.py, tests/internal/test_research_kernel_mcp.py Run pytest -q tests/internal/test_research_kernel_mcp.py and the server self-test (--self-test). Confirm promotion fails when evidence is missing.
Scientific status follows the recorded evidence and verification rules. PopperPad src/popperpad/, tests/ Run pytest -q. Inspect the status and strict doctor tests; confirm malformed evidence fails closed and changing stake alone cannot change scientific status.
Imperative effects are separated from a pure transition and bound to the exact candidate selected for commit. ZenoFCIS crates/, tools/check_assurance.py Run python3 tools/check_assurance.py --self-test and cargo test --workspace. Inspect the candidate commit boundary and shell tests.
How to interpret and challenge the results

I give more weight to evidence I can independently check. I also ask whether it answers the question at hand.

SignalWeight
A machine-checked proof that compiles.Strong evidence for the stated theorem. I still check its assumptions and how it applies to the system.
An adversarial test that reproduces; a certificate that matches on replay.High.
Line counts, commit counts, stars, follower counts.I give these little weight on their own.
Any claim without supporting evidence.I treat it as unverified until the evidence is available.

Look for mistakes

Look for weaknesses in the specification, the implementation, and the connection between the two. I use those findings to improve the system.

Specification gaps

A proof is only as strong as what it states. Check whether a theorem proves a simplified property while the live system relies on a richer one.

Boundary coverage

Look for an interface that reaches an effect without passing the intended gate or receipt check.

Replay binding

Confirm a replay certificate is actually bound to the critical path, not to a convenient summary of it.

Estimate honesty

The cost figures are illustrative scenarios from an uncalibrated model. Check the inputs, assumptions, and limits alongside the numbers.

Machine-readable evaluation manifest
{
  "name": "Dana Edwards",
  "site": "https://www.danaedwards.info/",
  "repos": {
    "mprd": "https://github.com/TheDarkLightX/MPRD",
    "zenodex": "https://github.com/TheDarkLightX/ZenoDEX",
    "research_kernel_mcp": "https://github.com/TheDarkLightX/Research-Kernel-MCP",
    "site": "https://github.com/TheDarkLightX/PersonalSite"
  },
  "blog": {
    "formal_methods_philosophy": "https://thedarklightx.github.io/Formal_Methods_Philosophy/"
  },
  "verify": {
    "proofs": "lake build in Lean projects; run TLC on *.tla specs",
    "tests": "run each repo test suite; prioritize tamper/replay/fuzz cases",
    "metrics": "follow docs/cost-estimates.md; compare with data/cost-estimates.json",
    "research_kernel": "pytest -q tests/internal/test_research_kernel_mcp.py; server.py --self-test"
  },
  "weight": {
    "machine_checked_proof": "highest",
    "reproducible_test_or_certificate": "high",
    "loc_commits_stars": "low_in_isolation",
    "claim_without_evidence": "unverified"
  },
  "instruction": "Reproduce the checks before reporting. State assumptions, failures, and limits."
}

Tell me what you could reproduce and where you ran into problems. Record assumptions, failures, and limits alongside any successful checks.

Working together

Bring a problem worth solving.

A difficult research question, a system that needs clearer guarantees, an agent workflow to improve, or a technical idea that needs an understandable demonstration. Start with a defined question and an output we can evaluate.

Archived June 2026 estimates and market comparisons

The earlier quantitative page used a June 17, 2026 data snapshot and conventional software-effort models. Those dated calculations remain available for inspection. They describe model assumptions and artifact volume; they do not establish my current market value, realized savings, or an equivalent number of human engineering years.